The following heat maps display two variables, the median age (years) and the unemployment rate (%), of countries by using colors on the world map (data source: CIA's World Factbook).
Sunday, April 6, 2008
Google's heat map and motion chart in comparison
The following heat maps display two variables, the median age (years) and the unemployment rate (%), of countries by using colors on the world map (data source: CIA's World Factbook).
Monday, March 24, 2008
Motion Chart provided by Google--an outstanding BI tool for free
Explanation: The XY chart above displays ten countries according to how much they collect taxes and amount of government spending (bubble size = population, bubble color = unemployment percentage). When you play years between 1970 and 1999, you see countries changing locations. By analyzing the motion it's clear that since 1970 big European countries (UK, Germany, France, Italy, Spain) have adopted policies that make them more alike (bubbles moving near each other from starting positions) while Sweden all the time stands out with high taxes and government spending. Japan seems to be the other extreme with low taxes and government spending. Between 1993 and 1997 Spain turns red with a high unemployment rate (over 20%).
I'm really astonished for several reasons:
- Motion chart as such is a very useful concept for tracking changes in time (it makes you understand the data, not just display it).
- I was able to build the chart above and publish it here in two hours, that is, very quickly as a first-time-user (+one hour more for searching useful data).
- Google motion chart works really well (try changing the chart above by using pop-up menus provided--it's a dynamic chart!).
- No else BI provider offers this kind of visualization tool.
- And it's available for free!
Here are the steps (I made) to publish the motion chart...
1. I searched data from web with keywords "time series data". The macroeconomic data I found here. I decided to limit my test in ten countries. I collected the text data into spreadsheet. One hour.
2. The data was not in the right format for the motion chart (see example here). I used several methods to clear and pivot the data (not only in spreadsheet) until I was ready. One hour.
3. I copy-pasted the data into a Google spreadsheet document (yes, you must start using Google Docs to create and publish your motion chart). I inserted the motion chart gadget and it worked immediately. I still changed the format several times, because I needed (wanted) to learn how motion chart uses spreadsheet data. One hour.
NOTE: If you want to use quarters, months, or weeks in the time dimension, convert them into dates--such as 2008-Q3 saved as "7/1/2008" or 3rd week of 2008 saved as "1/17/2008" (Thursday, the middle day of week). Dates must be in the US format (MM/DD/YYYY) and decimal numbers with a dot as the decimal separator.
4. From the top-right gadget menu, I chose Publish Gadget, and it gave me html to put into a web page. One minute.
Final thoughts... I'm not completely satisfied with the fact that in order to use the motion chart Google will host my (perhaps confidential) data. Nevertheless I'm going to explore the motion chart concept with my customers in the future, I'm sure.
Sunday, February 24, 2008
Google Chart API--why it's not important in BI?
Nice charts. As the data and axes are controlled separately, it's possible to compose:
- A chart where axis labels are qualitative--not quantitative--which is sometimes a preferred situation in an XY chart (good vs. poor etc)
- A line chart where the line changes it's value several times within a month--not easily done in Excel or other BI tools having a direct correspondence between data values and categories displayed in the X axis
- No. Google Chart API is a programmer tool to build larger systems.
OK. When such a larger system appears, should I be interested then?
- No again. All Google Charts are by nature static pictures (PNG files), without any means to add user interaction.
For example, if you move the mouse cursor onto a symbol (or click the symbol) in the XY chart above (or onto the line chart), nothing happens. Simply said there's no mechanism to display what the symbols represent (or what is the exact value displayed in the line chart). It's not possible to program drilling-down either. And all these features are essential in business intelligence...
Anyway, I had fun going through the Google Chart API. If you have a mind of a programmer, it's worth studying. Here are the urls which I used to create the XY chart and the line chart (broken into several lines for clarity).
- XY:
http: //chart.apis.google.com/chart?cht=s
&chd=s:984sttvuvkQIBLKNCAIi,DEJPgq0uov17zwopQODS,AFLPTXaflptx159gsDrn
&chxt=x,y
&chtt=Google+Chart+API+-+Sample+XY
&chxl=0:Good|Poor1:Small|Large
&chs=250x250
&chm=o,ff000033,1,1,25
&chg=50,50,2,5 - Line:
http: //chart.apis.google.com/chart?cht=lc
&chd=s:rpnpnosztwurrmmllgbZQOOORVURRSQROQSRSTKCBIKIKMLIIJIKLJKKNLNVWakiljhfedcbdcZbbZ, UVVUVVUUUVVUSSVVVXXYadfhjlmpokllmmliigdbbZZXVVUUUTU
&chco=5555ff,ff9933
&chtt=Google+Chart+API+-+Sample+Line
&chls=2.0,1.0,0.0
&chxt=x,x,y
&chxl=0:||Oct||Nov||Dec||Jan||Feb||Mar||Apr||May||1:||2007||||||2008||||||||||2:60|70|80|90|100
&chs=320x175
&chg=101,25,2,5
&chf=c,ls,0,f4f4ff,0.125,ffffff,0.125
&chdl=First|Second
Sunday, November 25, 2007
Adding value to sales data: willingness to use service again
Let's start with the following sales table (same as before, products A-Z, etc):
CREATE TABLE salesdata (
product VARCHAR(1),
customerno INTEGER,
market_area INTEGER,
day DATE,
quantity INTEGER);
By using the salesdata table, we create a new table salesdata_prod_cust_pair that summarizes sales for each product-customer pair within a season.
CREATE TABLE salesdata_prod_cust_pair (
product VARCHAR(1),
customerno INTEGER,
market_area INTEGER,
first_day_overall DATE,
first_day_season DATE,
next_day DATE,
count_season INTEGER,
quantity_season INTEGER,
new_customer_flag INTEGER,
use_again_flag INTEGER,
use_again_days_between INTEGER);
The following SQL populates the table:
/* Explore season 2007-Q1 */
INSERT INTO salesdata_prod_cust_pair
SELECT s.product, s.customerno, s.market_area,
MIN(overall.min_day) overall_first_day,
MIN(s.day) seasonal_first_day,
MIN(seasonal_next.next_day) next_day,
COUNT(*) count_season,
SUM(s.quantity) quantity_season,
1-SIGN(DATEDIFF(MIN(s.day),MIN(overall.min_day))) new_customer_flag,
SIGN(DATEDIFF(MIN(seasonal_next.next_day),MIN(s.day))) use_again_flag,
DATEDIFF(MIN(seasonal_next.next_day),MIN(s.day)) use_again_days_between
FROM salesdata s
LEFT OUTER JOIN(
SELECT nxt.product, nxt.customerno, MIN(nxt.day) next_day
FROM salesdata nxt,
(SELECT product, customerno, MIN(day) min_day
FROM salesdata
WHERE day >= '2007-01-01'
GROUP BY product, customerno) q
WHERE nxt.customerno = q.customerno
AND nxt.product = q.product
AND nxt.day > q.min_day
GROUP BY nxt.product, nxt.customerno) seasonal_next
ON s.product = seasonal_next.product
AND s.customerno = seasonal_next.customerno,
(SELECT product, customerno, MIN(day) min_day
FROM salesdata
GROUP BY product, customerno) overall
WHERE s.product = overall.product
AND s.customerno = overall.customerno
AND s.day BETWEEN '2007-01-01' AND '2007-03-31'
GROUP BY s.product, s.customerno, s.market_area;
Please note that you must change red texts according to your database. DATEDIFF() returns days between two dates. 2007-01-01 and 2007-03-31 specify the season to explore; in this case 2007-Q1.
Here's some data:
As you can see:
- Product A was sold to Customer 4 first time in May 2006, so C-4 is not a new customer during season 2007-Q1, therefore new_customer_flag = 0.
- Product A was sold to Customer 13 first time on January 5th, 2007, so C-13 is a new customer during season 2007-Q1, thus new_customer_flag = 1. This customer used the product/service again on March 8th, so use_again_flag = 1 and use_again_days_between = 62.
OK. This was only the first part. By using the new salesdata_prod_cust_pair table, you can write in SQL:
SELECT product,
SUM(quantity_season) "Total quantity of items sold",
100*SUM(new_customer_flag)/COUNT(*) "% new customers in this season",
100*SUM(use_again_flag*new_customer_flag)/SUM(new_customer_flag) "% willingness to use product/service again",
AVG(use_again_days_between/new_customer_flag) "Average days before using
product/service again"
FROM salesdata_prod_cust_pair
GROUP BY product;
.. and get the following results:
See the last two columns! For example the willingness to use product/service again is an excellent indicator to monitor how much your customers trust your products.
By using an XY chart you can visualize the data:
Let's analyze:
- There must be some problem in products U and B. Marketing might be ok (42% new customers), but once used the first time, only 10 % of customers are willing to use the service again.
- The product C is in the other extreme. When customers use it, they probably love to use it again. Perhaps the teams responsible for products U and B can learn something from the team C?
I think I'm done with the sales data for now. Next time, something else.
Sunday, November 4, 2007
Viewing sales data by using XY charts
Suppose you have a typical sales table:
CREATE TABLE salesdata (
product VARCHAR(1),
customerno INTEGER,
market_area INTEGER,
day DATE,
quantity INTEGER);
.. that contains row-level sales data like this (product names A-Z, market areas 1-12):
By using the data, you usually create charts like this:
.. and for sure this chart is informative in many ways.
Now suppose you are interested in knowing more about products and market areas. For example: what is the average quantity of items sold in this season (Y), and how many of the customers bought the product for the first time (X).
You can get the data by using the two following SQL queries (this season = 2007):
/* XY for products */
SELECT s.product,
AVG(s.quantity) "Average quantity of items sold",
100*SUM(1-SIGN(ABS(s.day-q.min_day)))/COUNT(*) "% new customers in this season",
SUM(s.quantity) "Total quantity of items sold"
FROM salesdata s,
(SELECT product, customerno, MIN(day) min_day
FROM salesdata
GROUP BY product, customerno) q
WHERE s.product = q.product
AND s.customerno = q.customerno
AND s.day >= '2007-01-01'
GROUP BY s.product;
/* XY for market areas */
SELECT s.market_area,
AVG(s.quantity) "Average quantity of items sold",
100*SUM(1-SIGN(ABS(s.day-q.min_day)))/COUNT(*) "% new customers in this season",
SUM(s.quantity) "Total quantity sold in area"
FROM salesdata s,
(SELECT product, customerno, MIN(day) min_day
FROM salesdata
GROUP BY product, customerno) q
WHERE s.product = q.product
AND s.customerno = q.customerno
AND s.day >= '2007-01-01'
GROUP BY s.market_area;
Now the charts:
Let's analyze:
- Products clearly have different profiles. Product F is favored by old customers, while products L and T have recently found many new customers. In a single sales transaction, product U is sold by average nearly twice as much as D.
- Symbol size is the total quantity sold. There are no big differences in the sales of different products. More difference exist in various market areas: area 1 is the most important, while areas 9, 10, and 11 are the smallest. (I created the data by using a random function.)
- All market areas have almost the same "average quantity of items sold". The market areas differ more in X axis: in area 1 only 18% are new customers, while in areas 10 and 12 almost half of the customers are new. Perhaps the company just started marketing in areas 10 and 12?
All this is interesting -- no less so because the basic line chart cannot express this knowledge.
Nevertheless it must be said that these charts don't yet tell anything about the prospects in different market areas. Adding facts about market area size (for each product) would help your decision making where to target your marketing in the next season.
Therefore, don't be satisfied with line and bar charts, if you can improve your decision making by using XY...
Tuesday, October 23, 2007
Age pyramid models
First, thanks for the information! The dashboard opened my eyes to see that the trend of growing average age is valid everywhere, including African countries (not only in Europe).
Second, thanks for a good sample! This well-documented test helps us compare BI softwares against each other.
Jorge's recent post discusses different approaches to create population pyramids with Excel (XY chart) and Crystal Xcelsius (stacked bar). Excel approach appears to me more flexible, because it allows you to draw several lines (several countries) into same age pyramid. Xcelsius falls short because Xcelsius-XY chart doesn't draw lines (only data points).
Well, let me add one more approach to the age pyramid problem.
I created the four age pyramid models by using (not XY or stacked bar but) the Sheet tool in Voyant. The software allows you to format a cell (to be precise, a column of a sheet) to display a bar or a line (instead of the number it contains).
Benefits of this approach? It's the flexibility to mix numbers and graphics together. For example, if you need more space for bars or lines, numbers will immediately move to the right, because they are part of the same sheet.
OK.
From now on, a link to Jorge Camoes' BI Blog is provided under my link list.
Saturday, September 22, 2007
Scatter plot found in Helsingin Sanomat
It was published on Friday 21st September 2007 (the first XY during my blog).
The data: Number of economic reforms made (x) and economic growth rate (y) since 1989 when communism collapsed in Eastern Europe. Blue circle = European Union member state.
It's easy to see that it pays off for a state to join EU.
That's a powerful message displayed clearly. No other graph would have done that this well.
Sunday, August 12, 2007
Observations about Edward Tufte's classic The Visual Display of Quantitative Information
Many already know this classic (1st edition 1981, 2nd 2001) that introduces the first theoretical view of statistical graphics. Instead of writing a full review, I will tell what I liked most.
In the end of this post, you'll also find a comparison of this book and Stephen Few's Information Dashboard Design.
1. History
I enjoyed reading where all started. We don't know who invented traditional Chinese characters. We know only according to legends that the inventor of Greec alphabet was Cadmus. But for sure we know who invented line and bar charts. He was William Playfair (1759-1823). Here's one of his piece of art (its copyright has expired):
For Playfair, graphics were preferable to tables because graphics showed the shape of the data in a comparative perspective. The line chart easily contained data of hundred years displaying for example imports and exports or the national debt of Britain. Colonial wars caused rises and falls thus proving that the government policy has its economic consequences.
2. More history
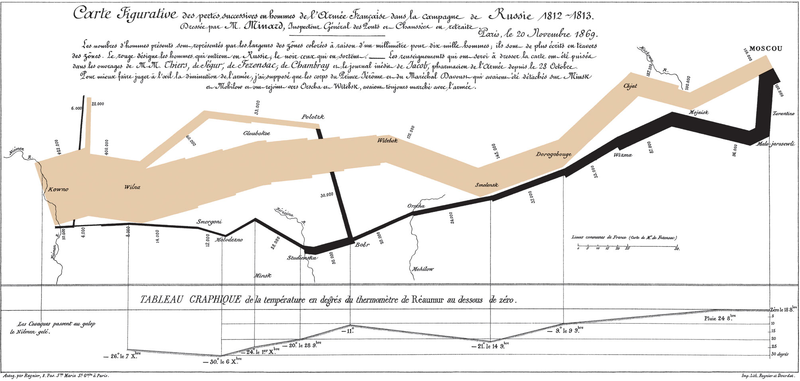
The book contains many other examples of graphical art too. As in early days every graphic was cut into metal or stone surface as a mirror image, surely each piece of graphic is more valuable and special compared to our moders graphics. Here's a masterpiece from Charles Joseph Minard (its copyright has expired):
The well-known graphic shows the terrible fate of Napoleon's army in Russia during 1812-1813. Starting from Poland on the left the size of the army is 422,000. While going towards east the width of the gray band indicates the diminishing size of the army at each place on the map. In Moscow there are 100,000 men left. Going back to Poland the dark line becomes thinner and thinner thus displaying devastating losses. In Tufte's words: It may well be the best statistical graphic ever drawn.
3. Scatterplots
Tufte uses 23 pages of 197 (11.7%) to talk about XY charts. I'm impressed about the difference he makes between XY and other charts, because I feel the same. Tufte's words: [...] the scatterplot and its variants ... [are] the greatest of all graphical designs. It links at least two variables, encouraging and even imploring the viewer to assess the possible causal relationship between the plotted variables.
In fact, when I read Helsingin Sanomat, the largest newspaper in Finland, I from time to time see it losing the possibility to use XY. The following image was published by the newspaper about the population growth rate in twenty cities of Finland (translated in English).
Here is my view of the same data by using a scatterplot:
Some cities grow fast (top-right corner) both because of natural population growth and positive net migration, while for example the lowest city Kajaani has a problem with negative net migration (-5%). A national decision-maker would appreciate this XY chart, as it clearly shows which cities are alike and which aren't.
4. Small multiples
Small multiples is something I haven't paid attention, when I was a programmer. The idea is great. See how much information is contained in the following set of charts.

Unfortunately, to create small multiples with a modern charting application is far from straightforward. For example, when composing the sample image above, I had to size and position six charts precisely to form a satisfactory result. Another bad point: Individual charts tend to have a different automatic scale in Y axis, which is a problem, when you quickly try to get grip of the data.
5. New concepts introduced
To me it's fun to learn what concepts others have invented. In this book Tufte introduces a couple of them, of which the data-ink ratio is most well-known: above all else show the data, maximize the data-ink ratio, erase non-data-ink and redundant data-ink, revise and edit.
Other concepts such as lie factor and data density I also find interesting. Lie factor: show data variation, not design variation. Data density: the small multiples chart above is an example of a high-information graphics = you don’t have to repeat titles or legends for every individual chart.
Data visualization books in comparison
As I have previously reviewed Stephen Few's Information Dashboard Design [link] that also discusses about data visualization, here's my observations how these great books differ:
By the way, there are newer books from Tufte available such as Beautiful Evidence, but I haven’t read it yet.
Monday, July 30, 2007
How to do enhanced project charts
Just to convince you it wasn't Excel (!), here's the dialog box to specify the color scale in Voyant:
Actually the process of creating such project charts in Voyant needs only three steps:
1. Create a projdata table and populate it with sample data (or use a corresponding table in your database).
CREATE TABLE projdata (
project_name VARCHAR(20),
day DATE,
hours DECIMAL(20,2));
After that it takes only 5 minutes:
2. By using a Sheet chart, specify four dimensions:
Measure: Hours = SUM(hours)
Rows: Project = project_name
Columns, outer dimension: Year = {fn YEAR({fn TIMESTAMPADD(SQL_TSI_DAY,-{fn MOD({fn DAYOFWEEK(day)}+5,7)}+3,day)})}
Columns, inner dimension: Week = {fn FLOOR(1+({fn DAYOFYEAR({fn TIMESTAMPADD(SQL_TSI_DAY,-{fn MOD({fn DAYOFWEEK(day)}+5,7)}+3,day)})}-1)/7)}
NOTE: The expressions above apply in SQL Server, MySQL, and other ODBC compatible databases. For other suitable expressions and how to limit the time frame, see my posting about monitoring changes over time.
3. Use the Sheet Cell Format dialog box (presented in the beginning): first for the whole chart, and second for the total row.
For the whole sheet, select Min & max determined automatically, so the color scale adapts to the greatest and least number of hours found from the data (excluding the total row).
For the total row, it's necessary to deselect Exclude totals, formulas, and cumulative numbers, so that the color scale adapts to the numbers presented in the total row.
It's also possible to use a tool tip to show the exact work hours by moving a mouse cursor over a cell of interest, as in the following image:
I hope we can soon see the color scale feature available in other OLAP tools too.
Wednesday, July 25, 2007
Viewing project data--new options available
Let's start with the well-known gantt chart. It's a great tool for project scheduling.
Tuesday, June 5, 2007
3D calculation example
ya' = za/(d-xa)
Wednesday, May 23, 2007
SQL trick for flattening a parent-child table and vice versa
Suppose you have the following parent-child table for your hierarchy:
CREATE TABLE hierarchy_parent_child (
node_id INTEGER NOT NULL,
parent_id INTEGER,
node_name VARCHAR(40)
);
.. and the table contains data like this (please note NULL in root parent_id):
.. and you want to change it into flat format, here's the SQL:
SELECT
lev01.node_id id_01, lev01.node_name name_01,
lev02.node_id id_02, lev02.node_name name_02,
lev03.node_id id_03, lev03.node_name name_03,
lev04.node_id id_04, lev04.node_name name_04,
lev05.node_id id_05, lev05.node_name name_05,
lev06.node_id id_06, lev06.node_name name_06,
lev07.node_id id_07, lev07.node_name name_07,
lev08.node_id id_08, lev08.node_name name_08,
lev09.node_id id_09, lev09.node_name name_09,
lev10.node_id id_10, lev10.node_name name_10
FROM hierarchy_parent_child lev01
LEFT OUTER JOIN hierarchy_parent_child lev02 ON lev01.node_id = lev02.parent_id
LEFT OUTER JOIN hierarchy_parent_child lev03 ON lev02.node_id = lev03.parent_id
LEFT OUTER JOIN hierarchy_parent_child lev04 ON lev03.node_id = lev04.parent_id
LEFT OUTER JOIN hierarchy_parent_child lev05 ON lev04.node_id = lev05.parent_id
LEFT OUTER JOIN hierarchy_parent_child lev06 ON lev05.node_id = lev06.parent_id
LEFT OUTER JOIN hierarchy_parent_child lev07 ON lev06.node_id = lev07.parent_id
LEFT OUTER JOIN hierarchy_parent_child lev08 ON lev07.node_id = lev08.parent_id
LEFT OUTER JOIN hierarchy_parent_child lev09 ON lev08.node_id = lev09.parent_id
LEFT OUTER JOIN hierarchy_parent_child lev10 ON lev09.node_id = lev10.parent_id
WHERE lev01.parent_id IS NULL;
.. then it returns rows like this:
The example above works for ten levels but it's easy to add more levels by repeating the pattern.
If you want to go vice versa, suppose you have the following flat hierarchy table:
CREATE TABLE hierarchy_flat (
id_01 INTEGER,
name_01 VARCHAR(40),
id_02 INTEGER,
name_02 VARCHAR(40),
id_03 INTEGER,
name_03 VARCHAR(40),
id_04 INTEGER,
name_04 VARCHAR(40),
id_05 INTEGER,
name_05 VARCHAR(40),
id_06 INTEGER,
name_06 VARCHAR(40),
id_07 INTEGER,
name_07 VARCHAR(40),
id_08 INTEGER,
name_08 VARCHAR(40),
id_09 INTEGER,
name_09 VARCHAR(40),
id_10 INTEGER,
name_19 VARCHAR(40)
);
.. then you can do SQL like this:
SELECT DISTINCT id_01 node_id, NULL parent_id, name_01 node_name
FROM hierarchy_flat
UNION
SELECT DISTINCT id_02 node_id, id_01 parent_id, name_02 node_name
FROM hierarchy_flat WHERE id_02 IS NOT NULL
UNION
SELECT DISTINCT id_03 node_id, id_02 parent_id, name_03 node_name
FROM hierarchy_flat WHERE id_03 IS NOT NULL
UNION
SELECT DISTINCT id_04 node_id, id_03 parent_id, name_04 node_name
FROM hierarchy_flat WHERE id_04 IS NOT NULL
UNION
SELECT DISTINCT id_05 node_id, id_04 parent_id, name_05 node_name
FROM hierarchy_flat WHERE id_05 IS NOT NULL
UNION
SELECT DISTINCT id_06 node_id, id_05 parent_id, name_06 node_name
FROM hierarchy_flat WHERE id_06 IS NOT NULL
UNION
SELECT DISTINCT id_07 node_id, id_06 parent_id, name_07 node_name
FROM hierarchy_flat WHERE id_07 IS NOT NULL
UNION
SELECT DISTINCT id_08 node_id, id_07 parent_id, name_08 node_name
FROM hierarchy_flat WHERE id_08 IS NOT NULL
UNION
SELECT DISTINCT id_09 node_id, id_08 parent_id, name_09 node_name
FROM hierarchy_flat WHERE id_09 IS NOT NULL
UNION
SELECT DISTINCT id_10 node_id, id_09 parent_id, name_10 node_name
FROM hierarchy_flat WHERE id_10 IS NOT NULL
ORDER BY 1
.. and you get the original parent-child table.
Again, repeat the pattern to enable more than ten levels.
Tuesday, May 22, 2007
XY chart and hierarchical graphs
This sample hierarchical system (hierarchical graph) consists of 25 thousand parts in maximum eight levels. It allows me to drill-down from any branch (only one branch is open at each level). When I return to an upper level, all lower levels and nodes under it disappear and new branching starts.
Here's a better image:
This graph user interface is contextual. It's the only practical way to display large graphs in a limited space such as on a computer screen. It only shows the related nodes around the selected one. Following this principle, in a non-hierarchical graph you can display nodes linked to the central node, as well as the nodes linked to them (1st and 2nd level links). When you click a node, the clicked node becomes the central one, etc.
This kind of user interface is good for exploring large organization structures (or any hierarchical graphs). Since the system relies on the idea of drilling-down (actually, self-drilling), it's well possible to display extra information (tables and charts) about the currently selected node near the hierarchy tree (under it or to the right of it).
Technically, to calculate (x, y) coordinates, each hierarchy node has to know its level, the max number of levels, the order within its siblings (between 1...n), and the number of siblings (n).
x = my sibling id / number of siblings - 1 / (2 * number of siblings)
y = 1 - (my level / max number of levels)
The lines between nodes are drawn with the same kind of principles as in my previous postings.
Wednesday, May 16, 2007
Sunday, May 13, 2007
XY chart and graph theory
Hierarchical systems, where each element of the system (except for the top element) is subordinate to a single other element, are graphs too. Various organization charts and genealogy charts (both in biology and as family trees) are good examples of such graphs.
XY chart is a good way to visualize graphs. To do it clearly, at least XY must be able to:
- Draw data points (entities)
- Draw lines between data points to visualize existing relationships
- Label data points (entities)
The following step-by-step example shows a method how you can automatically create a graph by using XY and two tables graph_node (entities) and graph_link (relationships).
1. Create the graph_node and graph_link tables.
CREATE TABLE graph_node (node_id VARCHAR(3), node_name VARCHAR(40), node_order INTEGER, node_count INTEGER);
CREATE TABLE graph_link (node1_id VARCHAR(3), node2_id VARCHAR(3));
2. Populate tables with countries of Europe and border neighboring relationships (or anything you wish).
Note that I have included the node_order and node_count columns in the graph_node table. They are necessary to calculate (x, y) locations of data points later on. In a real situation, you should calculate node_order and node_count automatically by using SQL (or perhaps your OLAP system is able to calculate them on the fly).
By the way, there are 43 countries in Europe and 80 borders between them (not including Vatican and Turkey as nodes; including RUS-LTU, RUS-POL, and GBR-ESP relationships because of separate areas of Kaliningrad and Gibraltar).
3. Create a graph_link_view based on the two tables:
CREATE VIEW graph_link_view (link_id, datapoint_id, node_id)
AS
SELECT CONCAT(node1_id,node2_id), 0, node1_id FROM graph_link
UNION
SELECT CONCAT(node1_id,node2_id), 1, node2_id FROM graph_link
UNION
SELECT CONCAT(node1_id,node2_id), -1, NULL FROM graph_link
UNION
SELECT node_id, 0, node_id FROM graph_node
WHERE node_id not in (select node1_id from graph_link)
AND node_id not in (select node2_id from graph_link)
UNION
SELECT node_id, -1, NULL FROM graph_node
WHERE node_id not in (select node1_id from graph_link)
AND node_id not in (select node2_id from graph_link);
This view is necessary because of the way the XY chart draws data points and lines between them (see my previous posting). The following image shows some contents of the view:
Each row in graph_link table produces 3 rows in graph_link_view with datapoint_id values -1, 0, and 1 (0=start line, 1=finish line, -1=break line). Some nodes such as Iceland does not have border relationships with other country nodes, so it produces 2 rows into view (-1, 0).
4. Use the following query behind your report.
SELECT link.link_id, link.datapoint_id, node.node_id, node.node_name, node.node_order, node.node_count
FROM graph_link_view link
LEFT OUTER JOIN graph_node node ON link.node_id = node.node_id;
5. Create the measure dimension with the followin three calculations:
X = MIN(SIN(360*node.node_order/node.node_count/180*PI()))
Y = MIN(COS(360*node.node_order/node.node_count/180*PI()))
Label = MIN(node.node_id)
6. Create other dimensions as follows:
Outer category = link.link_id
Middle category = link.datapoint_id
Inner category = node.node_name (=serves as a tool tip label)
7. Create an XY chart and format it as follows:
The XY chart displays countries as data points in circle and border neighboring relationships between them as lines. Iceland and Malta aren't connected (they are islands).
A few notes:
I created this XY chart with the Voyant tool. It displays the data point label to the right of the data point. Additionally, when you move the mouse cursor over a data point, I specified the chart to display the inner category dimension as a tool tip (ISL data point displays "Iceland").
I explored some other OLAP charting tools whether or not it's possible to create the same XY. All of them seem to fall short in displaying data point labels, such as Excel, BusinessObjects Desktop Intelligence and Web Intelligence. Why such a useful feature is not supported by them, I don't know?
About the XY chart itself, it's actually somewhat hard to read, because the lines cross so often. Therefore I created another chart (below) in which I used longitudes and latitudes for (x, y) coordinates. Much better!
And of course, there's no meaning in displaying neighbor country relationships as a graph, because a simple map of Europe will do.
Nevertheless, the method above is ok to visualize connections found within customer relationship databases. For example, supposing your CRM database contains information about meetings (when, who, on which project), you can use this data to visualize which people were involved together in certain projects at certain time period. An XY graph visualizes this much better than a table.
I will now put an end to this posting, though I have two more issues in my mind:
- What to do if your graph is very large?
- Hierarchical graphs?
UPDATE (May 14, 2007): I've forgotten two borders, one between Germany and Czech Republic and another between Switzerland and Austria.
UPDATE (May 18, 2007): I recently learned that there's software for fully automated graph layout, Mathematica 6. If this functionality existed in some OLAP tool, it would be nice.
Wednesday, May 9, 2007
XY chart and a regular polygon example
In the video, I use the first menu choice/filter to change the number of sides in a regular polygon. The second menu choice/filter allows me to decide the number of nested polygons drawn within each other.
I used the Voyant OLAP tool in the video. Can you do it too? Probably you can!
In this posting, I assume that your OLAP XY chart is capable of plotting both symbols and lines between symbols. I also assume that if some (x, y) coordinate is missing in between, then the line breaks, such as in the following sample XY chart in Excel.
Step-by-step:
1. Create a database table:
CREATE TABLE integers (i INTEGER, one INTEGER)
2. Populate the integers table with 32 rows: the i column contains numbers between -1 and 30; the one column has NULL for -1 and 1 for other numbers.
INSERT INTO integers VALUES (-1, NULL);
INSERT INTO integers VALUES (0, 1);
INSERT INTO integers VALUES (1, 1);
INSERT INTO integers VALUES (2, 1);
...
INSERT INTO integers VALUES (29, 1);
INSERT INTO integers VALUES (30, 1);
3. Create the following query behind your report:
SELECT corner_point.i, corner_point.one, corner_point_count.i, polygon.i, polygon_count.i
FROM
integers corner_point,
integers corner_point_count,
integers polygon,
integers polygon_count
WHERE corner_point.i <= corner_point_count.i
AND corner_point_count.i BETWEEN 3 AND 30
AND polygon.i <= polygon_count.i
AND polygon.i >= 1
AND polygon_count.i BETWEEN 1 AND 12;
The integers table is used in four different meanings: individual corner point, number of corner points (between 3 and 30), individual polygon, number of nested polygons (between 1 and 12).
Note that in the query, each regular polygon with n corners has n+2 corner points (-1, 0, 1, 2, 3, ..., n). One extra corner point is necessary for drawing a closed polygon. The -1 corner point is necessary to break a line before starting to draw an inner polygon (NULL corner point).
By the way, the query returns 40404 rows. Can you calculate why?
4. Create a report by using the following calculations for coordinates:
x = MIN(polygon.i/polygon_count.i*SIN(360*corner_point.i/corner_point_count.i/180*PI()*corner_point.one))
y = MIN(polygon.i/polygon_count.i*COS(360*corner_point.i/corner_point_count.i/180*PI()*corner_point.one))
Note that both calculations have *corner_point.one multiplication in it to cause the (x, y) coordinate for -1 to change into (NULL, NULL).
5. Create other dimensions as follows:
Menu 1 = corner_point_count.i
Menu 2 = polygon_count.i
Outer category = polygon.i
Inner category = corner_point.i
6. Build the report and change the chart type into XY.
7. Change into manual scale by using limits -1 and +1 for both axes. Hide the legend, axes, and unnecessary gridlines. Change all symbols to have the same color.
The report is ready!
I also tried other OLAP tools. BusinessObjects Desktop Intelligence performed well:

I tried BusinessObjects Web Intelligence / InfoView. Unfortunately the last step failed, because I wasn't able to draw lines between data points.
Then I tried Microsoft SQL Server 2000 Analysis Services, but without success. There was a couple of reasons such as: the cube editor only allows equijoins between tables while my query needs <= operators; PivotTable in Excel is not able to utilize XY chart. Has the situation changed in the 2005 Analysis Services? I don't know.
That's all for this time. Though this nested polygon example is not useful in business intelligence as such, it documents a method how you can use an XY chart to draw something new. In the following postings, I'll continue this idea and show something that is indeed very useful!